One thing that bothers me about long-running AI agents is context compaction.
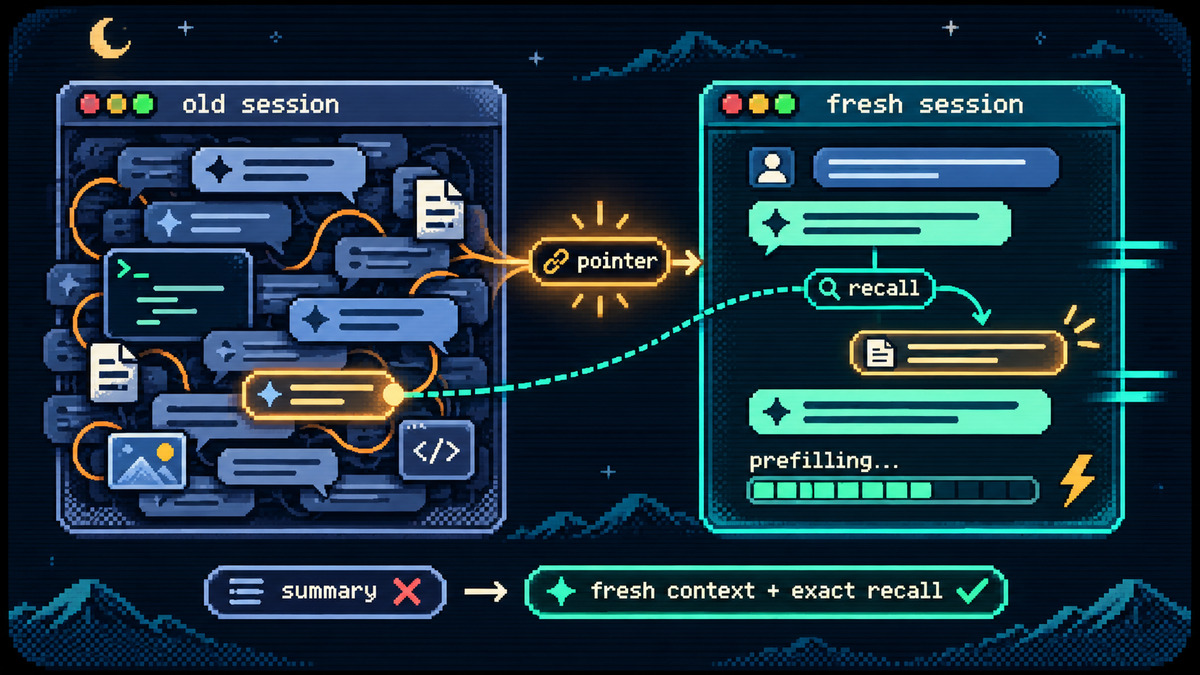
When the context window fills up, most agent harnesses ask an LLM to summarize the conversation and continue from there. It works, but summaries lose details, and after a few rounds of summarizing summaries, things can drift quite a bit.
The funny thing is that we already have the entire conversation stored on disk. Why not just let the agent look things up when it needs them?
I came across Alexander Yue’s work on context retrieval and liked the approach, so I built fresh-session-continuation, an experimental extension for Pi.
Instead of traditional compaction, it creates a small pointer to the previous conversation and automatically starts a fresh session. The new session knows what the agent was working on, where it left off, and where to find the previous conversation. It then continues working automatically, without you having to do anything.
The new session starts prefilling its context again, but because it’s starting with a much smaller, cleaner context rather than carrying around a huge conversation, the initial prefill should be significantly faster. The context then grows naturally as the agent continues working.
If the agent needs something from earlier, it can retrieve the exact information using the recall and recall_get tools. For example, if a build failed 100 turns ago with a specific error, the agent can search the previous session for that error and retrieve the original tool output instead of relying on a summary that might have lost the details.
No expensive LLM call for compaction, no summaries of summaries, and no need to manually restart or explain things again.
This is still experimental. I’ve done some initial testing, but I need to run more real-world tests to understand how well it holds up across long sessions and multiple continuations, and whether retrieval consistently works better than traditional compaction.
It doesn’t eliminate context limits, and retrieval still costs tokens, but I like the direction: I’d rather have an agent retrieve the actual information it needs than rely on an increasingly lossy summary.
If you’re using Pi and want to experiment with it:
pi install npm:fresh-session-continuation
It’s open source and available on GitHub and npm.
Maybe the solution to context limits isn’t better summarization, but better retrieval.